
What Is Conversational AI? How It Works in Chat and Voice
Conversational AI holds a back-and-forth conversation by text or voice and acts on what people ask. Here's how it works, where voice gets hard, and how to judge one.
Chatbots, voice assistants, and the AI agents that answer support lines can all hold a conversation, but they don’t work the same way. Conversational AI is software you can talk to in plain language, by typing or speaking, that remembers what’s been said and acts on what you ask. Newer AI agents run on a large language model connected to business systems, so they can do what you asked instead of walking you through a scripted menu.
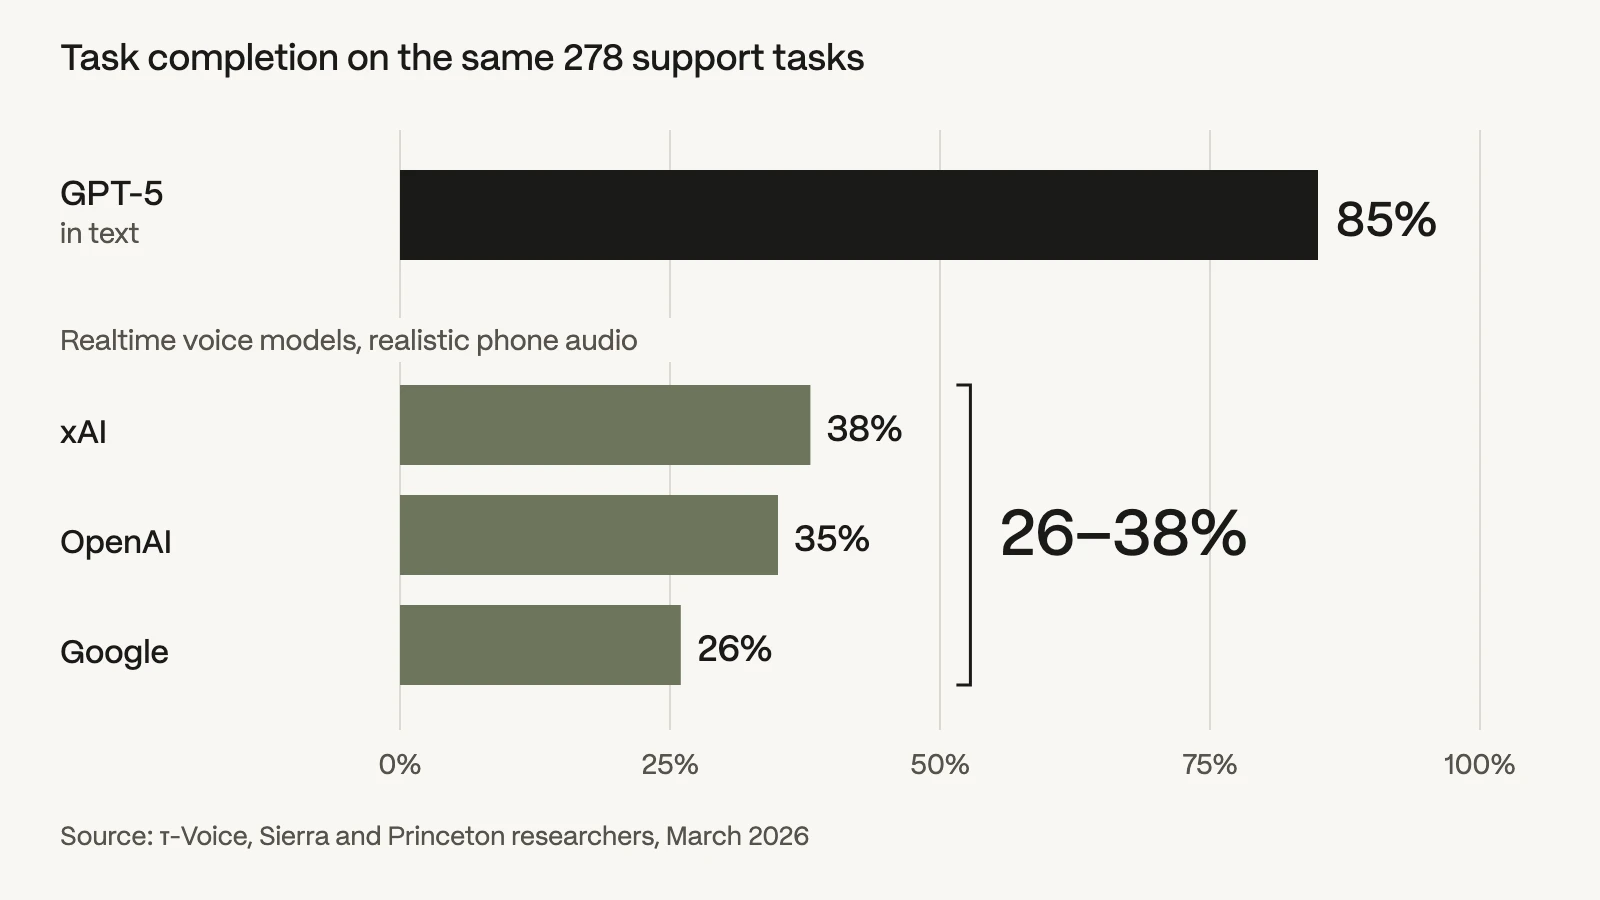
With newer models, sounding fluent is the easy part. We judge conversational AI by whether the task gets done every time someone asks, even with the background noise, accents, and frustration real users bring. Voice AI is where that bar gets hard to clear. τ-Voice, a March 2026 benchmark from Sierra and Princeton researchers, tests whether AI agents finish 278 retail, airline, and telecom support tasks, in text and in voice. GPT-5 finished 85% in text. The realtime voice models it tested, from OpenAI, Google, and xAI, finished only 26% to 38% of the same tasks once callers had accents, background noise, and phone-line compression.
Here’s where that gap comes from, and how to test for it.
How conversational AI works
A conversation is a series of turns, and every turn runs the same loop. The system takes in what the person typed or said, works out what they want, updates what it knows about the conversation, and decides whether to answer, ask a follow-up, act in a business system, or hand the person off. Then it replies.
In a modern system, a large language model does the understanding and the reply, and it acts through tool calls. The model asks for a function such as issue_refund, the application runs it against the real system, and the model turns the result into the answer. That’s the difference between an assistant that explains your refund policy and one that issues the refund.
Context is what makes it a conversation instead of a series of searches. The system carries state from turn to turn: who the person is, whether they’ve verified their identity, what they asked three turns ago, and what it has already done. A follow-up like “and the order before that?” only works if the system remembers which order “that” was.
Older systems split this loop in two. Natural language understanding (NLU) matched what the person said to a known request, and natural language generation (NLG) wrote the reply. Today an LLM does both jobs in one model.
Conversational AI vs chatbots and generative AI
Remembering and acting are also what separate conversational AI from the two terms it’s most often confused with. A chatbot is an interface and conversational AI is a capability, so a modern chatbot can be conversational AI while a decision-tree bot isn’t. Generative AI is the model. Conversational AI is the system built around that model, which holds the conversation’s state, calls tools, follows policy, and knows when to hand off.
Give three generations of systems the same message and the difference is obvious: “My order arrived but one item was wrong and I also have a question about the charge.”
| Generation | How it picks the next turn | What it does with that message |
|---|---|---|
| Scripted menu | Follows a fixed tree of options | Makes the person choose “Orders” or “Billing” and start over for the other |
| Intent bot | Matches each turn to one predefined intent, learned from example phrases | Picks one intent, so half the request goes unanswered |
| LLM agent with tools | Reads the whole message, plans, and calls tools | Looks up the order and the charge, and answers both parts |
That third generation is what most teams mean by an AI agent. Put one on a phone line, and the whole loop has to run in real time.
How conversational voice AI works
Conversational voice AI is the same loop running over a live audio stream, usually a phone call. Now the system also has to hear the caller, tell when they’ve finished, and answer fast enough to sound natural. The standard design chains three models (speech-to-text, then an LLM with tools, then text-to-speech), and every link adds time and another way to fail.
An AI voice assistant answers questions by voice. A voice agent also acts: it looks up the order, books the slot, or updates the record. On a support line, its tools decide what it can do, and anything outside them goes to a person.
A call moves through five stages, and the chain’s three models are the last three. For the two speech stages, we’ve added numbers from our public benchmark, which ranks voice models from almost 40 providers on audio that sounds like real calls. Both numbers are 30-day averages, for the 30 days to October 28, 2026.
- Phone audio. The caller’s voice arrives compressed. Twilio, for example, streams calls as 8 kHz, one-channel μ-law audio.
- Turn detection. The system decides when the caller has finished talking, either after a stretch of silence or from the words said. People pause mid-sentence, so a wrong guess means the agent cuts in or sits silent.
- Speech-to-text. The audio becomes words. Deepgram Nova 3, fifth-fastest of the 28 models ranked on speed on our speech-to-text leaderboard, delivered the final transcript 86 ms after the speech ended.
- The LLM and tools. The same understand-and-act loop as in text.
- Text-to-speech. The reply becomes audio. Cartesia Sonic 3.5, 20th of the 32 models on our text-to-speech latency leaderboard, took 291 ms from the start of synthesis to the first sound you can hear.
The yardstick is ordinary human conversation. In a study of 10 languages, people most often left 0 to 200 ms between turns. Speech synthesis alone took longer than that in our benchmark, and it’s one stage of five.
Speech-to-speech models skip the chain. They start from a text LLM and are trained to take audio in and send audio out directly, with no transcript in between. Adapting the model to audio costs it some reasoning. Neil Zeghidour, co-founder of the open science research lab Kyutai, put it bluntly in our interview: the speech model “will be much dumber than the original text model you started from.” The realtime voice models in τ-Voice work this way, and even with clean audio the best of them finished only 51% of the tasks. The chain is still the production standard.
Example: one customer support call
You’ll find conversational AI answering support calls and chats, booking appointments, checking order status, and opening claims. One support call shows every part of the definition at work, and where each part can break.
A caller wants to change their mailing address. Before the agent touches the account, it has to verify who they are. Halfway through, the caller adds: “Wait, why was I charged twice last month?”
Understanding starts with identity, which τ-Voice found was the dominant bottleneck for voice agents: they failed to transcribe names and emails. Background speech makes it harder. ai-coustics, which builds real-time audio models for voice AI, ran tests that it published with us: a TV or a second voice could land in the transcript as if the caller had said it.
Keeping context means the caller stays verified, and the address they spelled two turns ago is the one that gets saved.
Acting happens through a tool call that writes the new address to the account system. An agent that says “done” without changing the record has failed, however good it sounded.
Knowing its boundary matters when the double charge comes up. The agent can’t resolve a billing dispute, so it should say so and hand the caller to a person instead of guessing.
Benefits and limits of conversational AI
Routine calls like that address change are why teams deploy conversational AI. It picks up at any hour, takes the same request as often as it comes in, and lets people type or talk, whichever suits them. It breaks in the messy places: a noisy line, a spelled-out email address, a pause it mistakes for the end of a turn, and the task it got right once and wrong the next time.
Voice has a real speed edge. In a study by Stanford and University of Washington researchers, speaking was 2.93 times faster than typing short English messages, but it left more errors in the final text (1.30% vs 0.79%). That’s why a caller can explain a problem in seconds while an email address read aloud stays fragile.
Then there’s timing. In the τ-Voice runs with realistic phone audio, the voice agents took 0.90 to 1.15 s to respond after the user finished, far longer than the pause people usually leave between turns. Depending on the system, they also cut in before the user had finished on 14% to 84% of turns.
Consistency is what demos hide. The original τ-bench, a 2024 test from Sierra researchers, has an agent help simulated customers with retail and airline requests, then checks whether the database ended up in the right state. GPT-4o succeeded on fewer than half the tasks, and in retail it got the same task right on all eight tries less than 25% of the time.
A demo is one good run. Production is the same conversation thousands of times. Kwindla Hultman Kramer, creator of the open-source voice agent framework Pipecat, described what he hears from teams: “I got this prompt right, the 20 people at our company tested it and had a good experience, but then I put it in production and people did weird things.” Newer models call functions better in the first few turns, he added, but deep into a long conversation they’re “no better at all.”
How to evaluate conversational AI
Twenty happy colleagues aren’t a test plan. You evaluate conversational AI by running whole conversations against it and checking whether the task got done in the business system, not whether the agent sounded right. Start before launch, in chat and in voice, with simulated users who sound like your real ones. Then keep going on production conversations, because every real failure is a test you didn’t have yet.
That’s what we built Coval to do, for voice and chat agents on a single platform. In a simulated conversation, Coval plays a realistic user, talks to your agent end to end, and evaluates the conversation against criteria you define. On a voice call, that means judging the timing, the interruptions, and the audio as well as the words. Here’s how that covers the call from earlier.
- Identity capture. Personas set the simulated caller’s voice, accent, speaking style, interruption rate, and ambient noise, so the identity check meets callers who sound like yours.
- The account update. An API State metric calls your account API after the conversation and checks the saved address against the one the test expects, so “your address is updated” passes only if it was.
- The pivot and the handoff. An LLM Judge metric scores the conversation against a question you write: “Did the agent decline to resolve the billing dispute and transfer the caller to a person?”
The same metrics score your live calls. Send production calls in as uploaded conversations, and when one fails, turn it into a test case so your simulations catch that failure before the next release.
Krew builds voice agents for credit servicing. Building that kind of evaluation in-house could have taken quarters. With Coval, Krew was testing in days, and daily automated evaluations catch its regressions. Its rule: “Whenever there’s an edge case, we add it into our eval set and run it again.”
Our guides to conversational AI testing and testing voice agents cover test design in depth.
What conversational AI comes down to
It’s tempting to judge conversational AI by how it talks, because that’s what you notice. What counts is whether the task got finished, and the gap between text and voice is why you check both. Run your agent’s most common request as a simulated conversation in chat and in voice, and compare the outcomes.
Frequently asked questions
Is ChatGPT conversational AI?
Yes. ChatGPT is a chat app built on a large language model. You talk to it in plain language, and it remembers what you said earlier in the chat. A support agent built on the same kind of model goes further. It’s connected to one business’s systems, it follows that business’s policies, and it knows when to hand the person to a human.
What is a conversational AI platform?
A conversational AI platform is the software teams use to build and run these agents. It covers the model, the speech stack for voice, the connections to business systems, and the phone or chat channels. Our roundup of agent platforms compares the main options. Whichever you build on, test the agent the same way: whole conversations, judged by the outcome.