
Best Speech-to-Text Providers in 2026: 30+ Models Measured on Accuracy and Speed
We measure 30+ speech-to-text models on the same audio, timed the same way. Here are the five to try first for a voice agent, the full board, and how to confirm the pick on your callers.
Most voice agents start by turning the caller’s audio into text. Choosing among the best speech-to-text (STT) providers for that job comes down to two things your callers feel: how many of their words the agent gets wrong, and how long they wait after they stop talking for a final transcript it can act on. Coval doesn’t sell speech-to-text, but we measure 30+ STT models on the same audio, timed the same way, and publish the results on our public leaderboard.
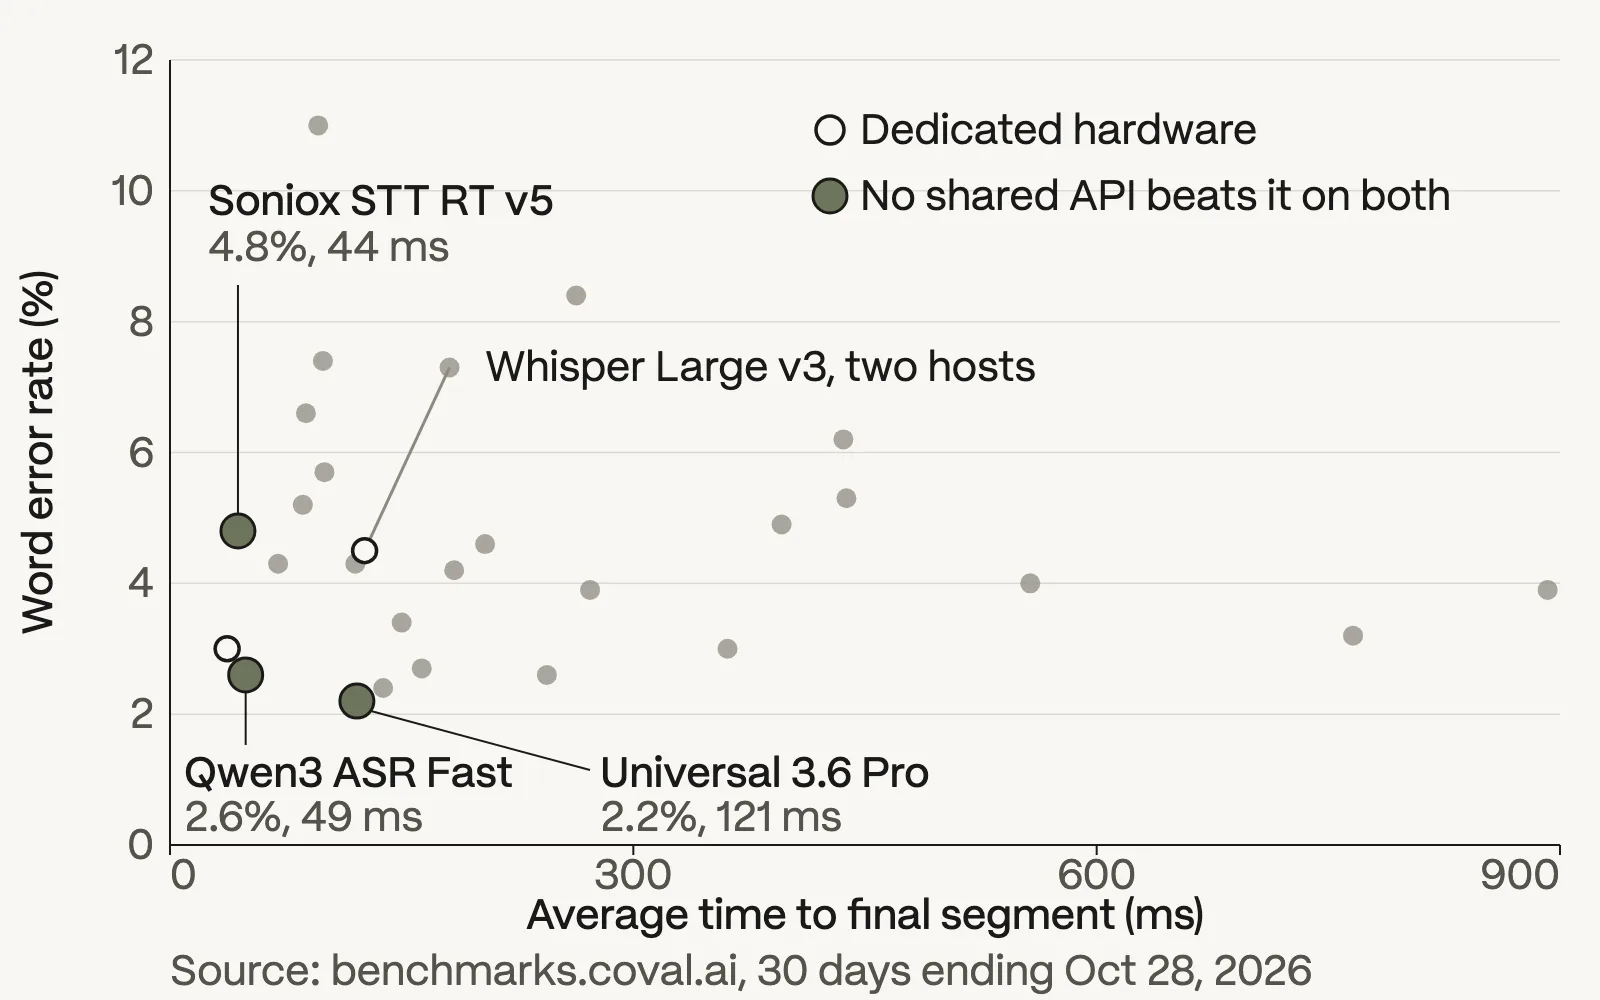
Quick answer: Over the 30 days ending October 28, 2026, AssemblyAI’s Universal 3.6 Pro was the most accurate, with a 2.2% word error rate (about one word in 45) and half its final transcripts back within 106 ms of the caller going quiet (its p50). Qwen3 ASR Fast, served by Nari Labs, was the best balance: a 2.6% error rate at a 45 ms p50. Soniox STT RT v5 was the fastest you can call without reserving your own hardware, with a 37 ms p50 and a 4.8% error rate; no model led on both accuracy and speed.
Two more round out our five picks: Inworld STT 1, the cheapest of the five on paid plans, and Deepgram Flux, which detects the end of the caller’s turn itself. Below, you’ll find the full board, how we measure, what phone audio and hosting change, and how to confirm the pick on your own callers.
The best speech-to-text providers for voice agents in 2026
Each pick wins on the one thing named in its Best for column, and we measure all five against the same two metrics:
Word error rate (WER) is the share of words a transcript gets wrong, whether swapped, dropped, or added, compared with a reference transcript of what was said, so lower is better.
Time to final segment is the wait, in milliseconds, from the moment the caller stops talking to the model’s final transcript for that turn. We report its p50 and its p95, the time that 95% of turns beat. When we rank speed, we use each model’s 30-day average, as our leaderboard does, and 28 of the 30 models were ranked on speed in this window.
The numbers come from our STT leaderboard for the 30 days ending October 28, 2026, and prices are each vendor’s list price per hour of audio.
| Pick | Best for | WER | Time to final segment, p50 / p95 | List price per audio hour |
|---|---|---|---|---|
| 1. Universal 3.6 Pro (AssemblyAI) | Accuracy | 2.2% | 106 / 222 ms | $0.45 |
| 2. Qwen3 ASR Fast (Nari Labs) | Accuracy and speed together | 2.6% | 45 / 69 ms | $0.12 |
| 3. STT RT v5 (Soniox) | Speed without reserved hardware | 4.8% | 37 / 70 ms | $0.12 |
| 4. STT 1 (Inworld AI) | Lowest list price | 4.3% | 66 / 108 ms | $0.10 ($0.15 on demand) |
| 5. Flux (Deepgram) | Built-in turn detection | 5.7% | 99 / 165 ms | $0.39 |
Universal 3.6 Pro is the most accurate speech-to-text model we measure
AssemblyAI’s Universal 3.6 Pro had the lowest word error rate of all 30 models on our board, 2.2%. It isn’t slow, either: final transcripts came back in 106 ms at p50 and 222 ms at p95. Its lead holds on phone audio too. When we run clean recordings through the compression phone networks apply, it stays first at 2.7%.
Choose it when a misheard word costs you more than a few milliseconds do: account numbers, medication names, street addresses, anything your agent has to act on exactly. The catch is price. At $0.45 an hour of streaming audio, it lists at nearly four times the price of the next two picks.
Qwen3 ASR Fast is the best balance of accuracy and speed
Qwen3 ASR Fast, Nari Labs’ hosted API for the Qwen3 ASR model, comes closest to having both. Its 2.6% word error rate ranks third of 30, and its final transcripts arrive in 45 ms at p50 and 69 ms at p95, third-fastest of 28 on average. The only two models that are more accurate, AssemblyAI’s Universal 3.6 Pro and Universal 3.5 Pro, take more than twice as long at p50.
It holds up on phone audio, rising to 3.4% and staying third. Nari lists the Fast tier at $0.12 per input audio hour. For most English voice agents, this is the model we’d test first.
Soniox STT RT v5 is the fastest without reserved hardware
Soniox’s STT RT v5 returned final transcripts in 37 ms at p50 and 70 ms at p95, second of 28 on average speed. The one model ahead of it runs on hardware reserved for a single customer. Among shared APIs, the kind you call without reserving anything, nothing finalizes faster on average. Its word error rate is 4.8%, 18th of 30.
Pick it when response time is the tightest part of your budget and your callers’ audio is clean, as in a web or app agent with a decent microphone. Soniox lists real-time transcription at $0.12 an hour. The catch is the phone line: through telephony compression, its error rate rises to 6.9%, 19th of 30. Soniox will retire STT RT v5 on December 15, 2026, and route its traffic to STT RT v6, so if Soniox makes your shortlist, test v6 on your own callers.
Inworld STT 1 has the lowest list price of our picks
Inworld AI lists STT 1 at $0.10 an hour on its paid plans ($0.15 on demand), the lowest price of our five picks. It doesn’t give up much for it: a 4.3% word error rate (15th of 30), and final transcripts in 66 ms at p50 and 108 ms at p95, fourth-fastest of 28 on average.
It also takes phone audio better than most. Through telephony compression, its error rate rises only to 4.8%, and its rank climbs from 15th to 8th. That makes it a strong fit for agents that transcribe a lot of call minutes, where cost per hour is the number you’re managing.
Deepgram Flux builds turn detection into the transcript
Turn detection is the agent’s call that the caller has finished speaking and it’s time to reply. Flux makes that call inside the STT: it sends an end-of-turn event once its confidence that the caller is done crosses a threshold you set, or after a silence timeout. The transcript and the signal to reply come from one model.
On our board, Flux returned final transcripts in 99 ms at p50 and 165 ms at p95, with a 5.7% word error rate. Deepgram lists it at $0.0065 a minute, or $0.39 an hour. It’s the pick when turn detection is the problem you’re solving. Phone audio is where it slips: its error rate rises to 8.0%.
All 30 models on our speech-to-text leaderboard
If the model you’re considering isn’t one of our picks, here’s where it stands. The table lists every model on our board, sorted by word error rate, with its average time to final segment (the 30-day average, which is how our leaderboard ranks speed). Rows marked dedicated run on hardware reserved for one customer; every other row is a shared API that serves many customers. Source: benchmarks.coval.ai, September 28 to October 28, 2026.
| # | Model | Host | WER | Average time to final segment (ms) |
|---|---|---|---|---|
| 1 | Universal 3.6 Pro | AssemblyAI | 2.2% | 121 |
| 2 | Universal 3.5 Pro | AssemblyAI | 2.4% | 138 |
| 3 | Qwen3 ASR Fast | Nari Labs | 2.6% | 49 |
| 4 | resonant-1 | Reson8 | 2.6% | 244 |
| 5 | Realtime Global | Reson8 | 2.7% | 163 |
| 6 | Gemini 3.5 Transcribe Live | Google Gemini | 3.0% | 361 |
| 7 | Qwen3 ASR 1.7b | Baseten (dedicated) | 3.0% | 37 |
| 8 | Chirp 3 | 3.2% | 766 | |
| 9 | Ink 2 | Cartesia | 3.4% | 150 |
| 10 | Linden 1 | Speechmatics | 3.9% | 272 |
| 11 | Chirp 2 | 3.9% | 892 | |
| 12 | GPT Realtime Whisper | OpenAI | 4.0% | 557 |
| 13 | Grok STT | SpaceXAI | 4.2% | 184 |
| 14 | Scribe v2 Realtime | ElevenLabs | 4.3% | 120 |
| 15 | STT 1 | Inworld AI | 4.3% | 70 |
| 16 | Whisper Large v3 | Baseten (dedicated) | 4.5% | 126 |
| 17 | Pulse | Smallest | 4.6% | 204 |
| 18 | STT RT v5 | Soniox | 4.8% | 44 |
| 19 | Daytona STT | Guava | 4.9% | 396 |
| 20 | Nova 3 | Deepgram | 5.2% | 86 |
| 21 | Voxtral Mini Transcribe Realtime 2602 | Mistral | 5.3% | 438 |
| 22 | Flux | Deepgram | 5.7% | 100 |
| 23 | Universal Streaming | AssemblyAI | 5.9% | Not ranked |
| 24 | Solaria 1 | Gladia | 6.2% | 436 |
| 25 | Nova 2 | Deepgram | 6.6% | 88 |
| 26 | Whisper Large v3 | Together AI | 7.3% | 181 |
| 27 | Flux Multilingual | Deepgram | 7.4% | 99 |
| 28 | Default | Gradium | 8.4% | 263 |
| 29 | Parakeet TDT 0.6B v3 | Together AI | 11.0% | 96 |
| 30 | Nemotron 3.5 ASR Streaming | Together AI | 13.0% | Not ranked |
Read it as a trade-off. Only three shared APIs have no rival that beats them on both accuracy and speed: Soniox STT RT v5, Qwen3 ASR Fast, and Universal 3.6 Pro. Every other shared API ranked on speed has one that’s more accurate and faster. Going from Soniox to Qwen3 to Universal, you trade speed for accuracy.
If you’re choosing among Deepgram, AssemblyAI, and OpenAI, the board is clear. AssemblyAI’s Universal 3.6 Pro is the most accurate of their models (2.2% at a 121 ms average), Deepgram’s Nova 3 and Flux finalize faster (86 ms and 100 ms) at 5.2% and 5.7%, and OpenAI’s GPT Realtime Whisper sits between them on accuracy, at 4.0%, but takes 557 ms.
How we measured, and why vendor numbers look different
Every model on the board hears the same audio and is timed the same way. The audio starts with 897 spontaneous voice-agent turns, fragments and filler words included, from the open benchmark data of Pipecat, an open-source voice agent framework. Public recordings add six more sets: clean read speech, accented speech, background noise, far-away microphones, clipped signals, and phone-line compression. Each run draws one set of clips and scores every model on that same set, and each of our five picks was scored on more than 25,000 clips in the window. Before scoring, we normalize both the reference and the model’s transcript, so “5” and “five” count as the same word.
The timing matters as much as the audio. For every provider, the same voice-activity model marks the moment the caller stops talking, and the timer runs from that mark to the provider’s final transcript. Connection setup is left out for everyone. Our methodology and code are open.
That design explains a gap you’ll see between our numbers and a vendor’s. AssemblyAI’s launch post for Universal 3.6 Pro charts our leaderboard for its accuracy, and reports a 537 ms median endpoint latency. Endpointing is AssemblyAI’s word for turn detection, and its 537 ms comes from that endpointer. Our method leaves provider endpointing out. A shared voice-activity model marks when the caller stopped talking, at the same moment for every provider, and the timer starts from that mark. For Universal 3.6 Pro, the final transcript arrived 106 ms after it at p50. The two figures aren’t measuring the same thing.
Before you compare any two latency figures, pin down five things: the event that starts and stops the clock, the time window, the statistic (average, p50, or p95), the exact model and endpoint, and the audio.
Phone audio and hosting change the numbers
The overall board is a starting point, and two things specific to your agent move it: the audio your callers send and the company serving the model.
For Universal 3.6 Pro, phone audio costs accuracy, not speed: its average time to final segment stays between 111 ms and 124 ms across all seven of our audio sets. Accuracy is another story. On our phone-codec set, every one of our picks makes more errors, and the spread between them grows from 2.2–5.7% to 2.7–8.0%. Universal 3.6 Pro and Inworld STT 1 each add half a point of error; Soniox and Flux add more than two. If your agent answers the phone, rank by that set rather than the overall board.
The host moves both numbers. The same model can be served on a shared API or on dedicated hardware, and we measure each host separately. Whisper Large v3 measured 4.5% WER and a 245 ms p95 on Baseten’s dedicated endpoint, against 7.3% and 563 ms on Together AI’s shared one. Qwen3 ASR 1.7b on Baseten’s dedicated hardware is the fastest model on the board, at a 37 ms average and a 21 ms p50, with a 3.0% error rate. Baseten bills dedicated deployments by GPU time rather than per audio hour, so that choice is about reserving capacity, not picking a line on a price list. As Cale Smith of our benchmarks team put it in a benchmarks AMA, “the server is just as important as the model in these instances.”
Both effects depend on your callers and your stack, which is why the last step belongs on your own calls.
How to choose: run your shortlist on your own callers in Coval
In the same AMA, Brooke Hopkins, Coval’s founder, described picking a model as a ladder: public benchmarks first, then your own benchmark of the “three to five” top models you’re considering, then task-specific evals of what your agent actually has to do. Our board is the first rung. Your callers’ accents, their phone lines, and the account numbers your agent has to catch decide the rest, and that’s the part Coval’s platform runs.
- Build a test set around what your callers say. A test set is a collection of scenarios for simulated callers to work through. Write them around the names, dates, and account numbers your agent must get right.
- Make the simulated callers sound like yours. In a simulation, Coval plays a realistic caller and talks to your agent end to end. A persona sets that caller’s voice, language, audio environment, and conversational behavior, with background noise from a built-in library or your own recordings. Our guides to testing across accents and audio quality show how to cover your caller mix.
- Run the same test set against each candidate. Stand up a build of your agent for each STT on the shortlist and run the same test set against every one, so the transcription model is the only thing that changes.
- Score the words and the outcome. Transcription Error measures transcription accuracy by comparing the conversation transcript with an independent re-transcription that Coval makes of the same audio, reported as a word error rate, so every candidate gets a score on the same callers. An API State check confirms what happened next: after the call, Coval queries your own API and compares the result with what should have happened, such as the account the caller named being the one that got updated.
- Keep scoring after launch. Once you choose, Coval scores your production calls on the same metrics and flags drift from your baseline as it starts, so you see it if a provider update begins costing you accuracy.
That’s a vendor bake-off the way Coval runs one: the same calls against every candidate, and a result you can show your team.
Start from your constraint, then let your callers decide
If accuracy decides, start with Universal 3.6 Pro. If you need accuracy and speed together, start with Qwen3 ASR Fast, and if speed comes first, Soniox STT RT v5. If cost per hour decides, start with Inworld STT 1; if you want turn detection from the same model, Deepgram Flux. Then run your shortlist past your own callers’ voices, phone lines, and account numbers before you commit. Speech-to-text is half of your agent’s audio path; our guide to the best text-to-speech providers covers the half your callers hear.
Frequently asked questions
Which speech-to-text provider is best for languages other than English?
The rankings above are on English audio. To compare providers in another language, run the same test set in that language against each one. Coval personas speak languages from Arabic and Bengali to Portuguese and Spanish, so you can see how each STT handles your callers and compare Transcription Error side by side. A vendor’s count of supported languages tells you where to start, not which one wins.
Should I self-host an open model like Whisper or use an STT API?
Self-host when cost, customization, or tail latency gives you a reason to; our post on self-hosted models walks through each. Then measure the host you’d actually use, because the same model can behave very differently on different hardware, as the Whisper Large v3 numbers above show. Choose the open model carefully too: on our board, Parakeet TDT 0.6B v3 measured 11.0% WER against 3.0% for Qwen3 ASR 1.7b.
Do I need a speech-to-text provider if I use a speech-to-speech model?
Only for a cascaded agent, which chains three models: speech-to-text transcribes the caller, an LLM decides the reply and calls any tools, and text-to-speech speaks it. A speech-to-speech model takes the caller’s audio and answers in audio, with no separate transcription step to choose. Our comparison of speech-to-speech vs cascaded architectures covers when each fits.
What does speech-to-text cost at 100,000 minutes a month?
100,000 minutes is about 1,667 hours of audio. At list prices, that’s about $750 a month for Universal 3.6 Pro ($0.45 an hour), $650 for Deepgram Flux ($0.0065 a minute), $200 each for Qwen3 ASR Fast and Soniox STT RT v5 ($0.12 an hour), and about $167 for Inworld STT 1 on a paid plan ($0.10 an hour; $250 at the on-demand rate).