
Best Voice And Conversational AI Agent Platforms in 2026: How To Pick Your Stack
Vapi, Retell, LiveKit, Sierra, LangGraph and coding agents solve different jobs. Build a shortlist around the work you need done, then compare the operating commitment and evidence of success.
An AI agent can sound convincing while leaving the job unfinished, like giving a polite reply without issuing a refund, or writing plausible code that breaks the build. Choosing an agent platform comes down to two questions a polished demo never answers: who maintains the workflow and how will you verify the promised outcome actually happened?
The right platform delivers the work you want to buy while leaving behind an operating burden your team can actually carry. Instead of ranking platforms from best to worst, we’ve put together a guide that compares platforms by job, breaks down true operating costs, and shows how to prove a finalist completes the task.
Best AI agent platforms by job
On paper, most AI agent platforms sound similar. What separates them is the job each one is built for and the work it leaves your team, so that’s how this guide compares them. Our public benchmarks cover a different layer: the AI models and providers that voice platforms build on, like speech-to-text and text-to-speech.
We put together this table to help you build an initial shortlist based on product fit and engineering ownership rather than marketing claims.
| Platform | Best-fit buyer | Reason to shortlist it | Operating commitment |
|---|---|---|---|
| Vapi | Engineers configuring a hosted voice agent | Swappable transcription, LLM, and voice providers | Wire up and maintain modular component configs and tool schemas |
| Retell AI | Teams launching customer calls and chat | Integrated prompt/flow builder with built-in testing and monitoring | Configure and validate conversation flows, call transfers, and webhooks |
| ElevenAgents | Teams pairing expressive voice with visual workflows | Native ElevenLabs voice channels, visual workflow design, and automated testing | Verify model latency and tool behavior across telephony and web channels |
| LiveKit Agents | Engineers writing real-time agents in Python or Node | Code-first media orchestration and turn detection (Cloud or self-hosted) | Write application logic and manage worker deployments |
| Pipecat | Python teams building custom real-time pipelines | Open-source (BSD-2) frame-based pipeline across any provider | Own the full Python application; budget STT/LLM/TTS and hosting separately |
| Sierra | CX leaders buying multichannel service outcomes | Deep system-of-record integrations and outcome-based pricing | Define strict contractual outcomes and verify backend system actions |
| Decagon | CX teams managing policy in natural language | Agent Operating Procedures (AOPs) across chat, voice, and email | Govern how policy owners edit procedures and audit automated actions |
| Parloa | Enterprise CX teams focused on release governance | Built-in Performance Lab simulations and Lens production monitoring | Run pre-release regression suites and manage enterprise telephony integrations |
| LangGraph | Engineers building stateful, long-running agents | Durable execution, state persistence, and human-in-the-loop checkpoints | Architect, code, and maintain graph orchestration and state storage |
| OpenAI Agents SDK | Developers building tool-using multi-agent handoffs | Lightweight Python primitives for guardrails, tracing, and sessions | Build and host the surrounding application and runtime environment |
| CrewAI / n8n | Teams automating internal multi-step business workflows | Structured multi-agent delegation (CrewAI) or visual system triggers (n8n) | Audit side effects and prevent brittle multi-agent loops |
| AWS / Google / Microsoft | Enterprises standardizing on an existing cloud stack | Native IAM identity, cloud guardrails, and enterprise channel integrations | Configure cloud permissions, data connectors, and governance policies |
| Claude Code / Codex | Software teams automating repo edits and PRs | Terminal, IDE, and cloud sandbox execution against real codebases | Review diffs, enforce CI checks, and manage repo access permissions |
AI agent platforms hand over different levels of autonomy to AI
Before comparing features, decide which responsibilities your team wants to own: conversation orchestration, runtime operations, or acceptance criteria.
| AI agent platform: Software that provides an environment for configuring, running, or managing agents that combine language models and tools to complete tasks. |
|---|
These three responsibilities frequently split across different owners or products:
- Orchestration determines how models, conversation state, and external tools interact (for example, state and workflow frameworks like LangGraph, CrewAI, or the OpenAI Agents SDK, as well as flow builders inside Vapi and Retell AI).
- Runtime operations keep the deployed service fast, available, and connected to telephony or chat channels (such as SIP trunking and telephony carriers like Twilio and Telnyx, WebRTC media infrastructure like LiveKit Cloud, or hosted voice runtimes like Vapi and Retell AI).
- Acceptance criteria define which outcomes and policy rules count as a verified success (enforced through simulation, observability, and evaluation platforms like Coval, Braintrust, LangSmith, and Arize Phoenix).
A vendor can run the voice infrastructure while your engineers own the tool logic and your QA team owns the evaluation rubric. Your procurement checklist should name an internal owner for every layer. Assuming “the vendor handles the AI” leaves a dangerous gap if nobody owns the refund policy or signs off when a prompt change alters agent behavior. Our voice architecture guide breaks down the technical components behind this split.
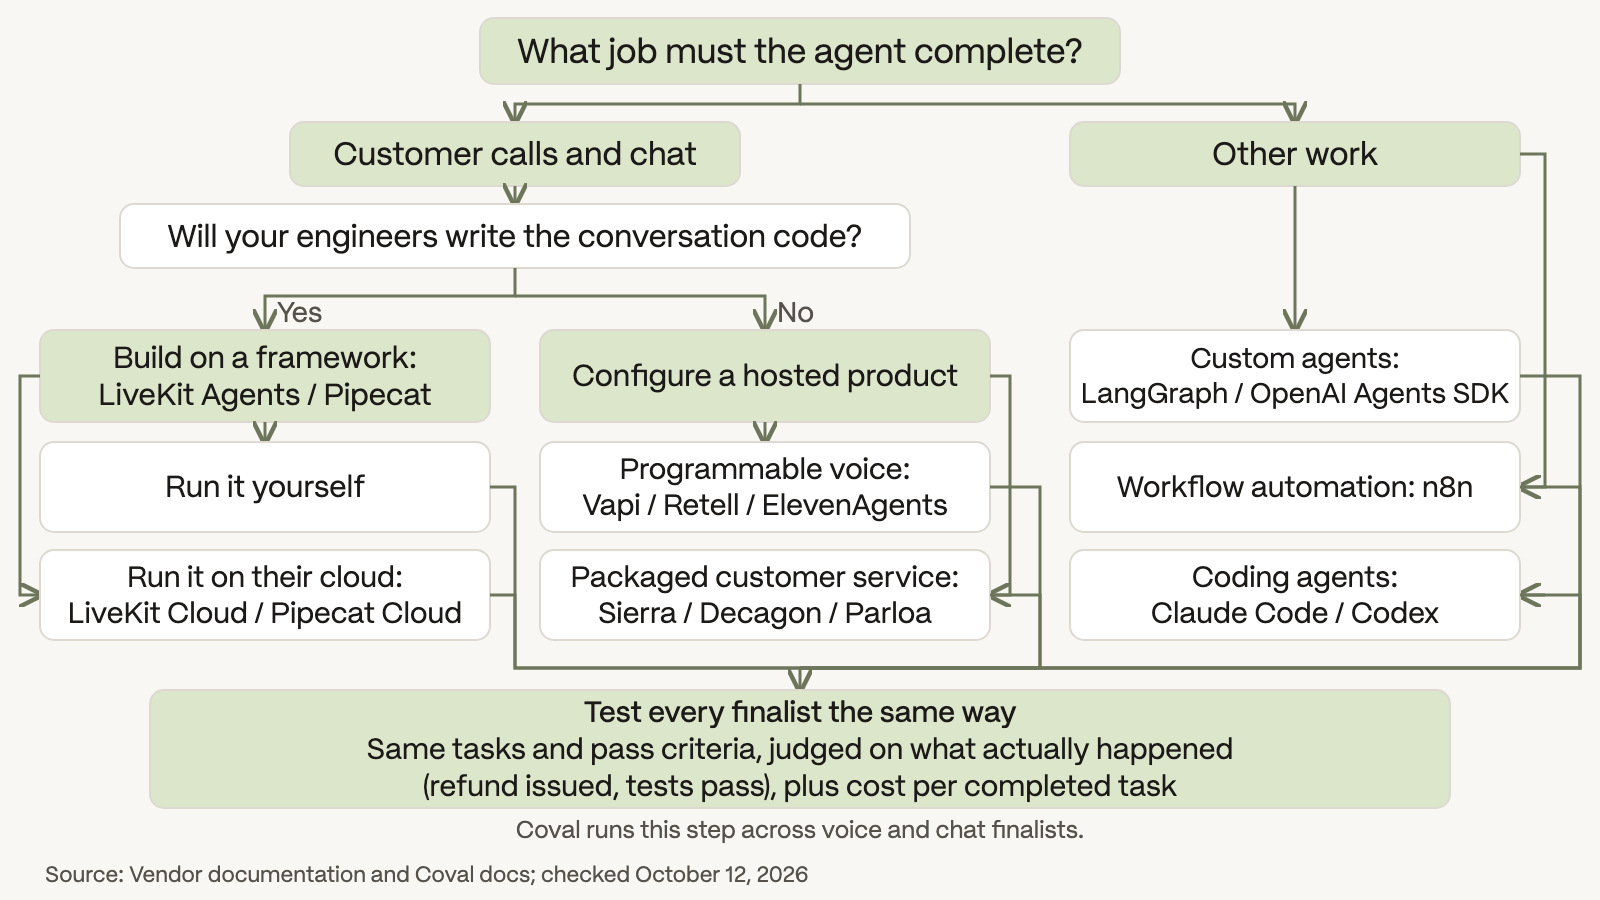 Pick the category by what your team will build and run, then hold every finalist to the same test: did the task actually get done, and what did each completed task cost?
If your team wants to configure conversation behavior while a vendor manages the underlying voice infrastructure, start with managed voice platforms.
Managed voice platforms run the voice stack while you configure the agent
Managed voice platforms are best for engineering teams that want to configure prompts, flows, and tool integrations without running real-time media servers. Shortlist candidates based on what your team needs to customize, then test how each platform handles a realistic change.
- Choose Vapi when mixing and matching the transcriber (STT), model (LLM), and voice (TTS) is central to your product.
- Choose Retell when an all-in-one voice/chat workflow, using either a single prompt or a visual conversation-flow canvas, matches your calls.
- Choose ElevenAgents when expressive voice synthesis, visual workflow design, telephony/web channels, and built-in experiment testing belong in one service.
The core distinction between Vapi and Retell is where your engineers spend their time: fine-tuning modular providers (Vapi) or designing the conversation flow (Retell). Neither removes your responsibility for backend tool reliability and policy enforcement. Read our deep-dive Vapi review and Retell review for granular configuration trade-offs.
How to stress-test a demo: Ask the engineer running the POC to change a concrete requirement live, such as adding a second item to a refund, modifying a tool schema, or passing context across a warm transfer. Note whether that change requires editing a prompt, rewiring a flow node, swapping a provider config, or writing external webhook code. That tells you exactly what your team will spend time maintaining in production.
Voice frameworks trade operating work for control
When your product requires custom turn-taking, proprietary audio processing, or deep application state that managed configs cannot express, move to a voice framework.
- LiveKit Agents is the strongest starting point for teams writing real-time voice or video agents in Python or Node. You write the orchestration and turn-handling logic in code, and you can deploy either to LiveKit Cloud or your own infrastructure.
- Pipecat fits Python teams that want an open-source (BSD-2) frame-based pipeline to wire together providers directly. You can self-host or deploy to Pipecat Cloud, just remember that an open-source license doesn’t make the STT, LLM, TTS, telephony, or hosting free.
Only pick a framework if you need custom orchestration that managed platforms can’t support. “More flexibility” isn’t a good enough reason to take on deployment pipelines, credential rotation, worker scaling, and on-call incident response. Write down who owns those operational jobs for your target environment before committing.
Customer-service platforms package the business workflow
If you want to buy a finished customer-service workflow rather than developer building blocks, look at packaged CX platforms. Don’t dismiss this category as “low customization.” Instead, evaluate how clearly your team can express policies, connect systems of record, and audit customer outcomes.
- Sierra fits enterprises buying multichannel service outcomes across voice, chat, email, and WhatsApp. Because Sierra offers outcome-based pricing, how your contract defines a “resolved issue” is just as important as the software itself.
- Decagon stands out when CX operations teams want to write and maintain service policies directly using natural-language Agent Operating Procedures (AOPs). Evaluate how easily a policy owner can update an AOP and verify the resulting API actions.
How to evaluate CX vendors: Bring an edge-case policy exception to the demo, not just the happy path. Ask the vendor to show exactly where customer eligibility is checked, which backend system is mutated, and what context a human agent sees during an escalation. And if you negotiate outcome-based pricing, align the billing definition with your internal QA rubric; don’t assume a vendor’s default “resolution” matches your standard for a completed refund.
Custom chat agents, automation, and cloud services
When the job is an internal workflow, stateful background automation, or an enterprise cloud deployment, voice infrastructure platforms are the wrong tool. Pick frameworks and cloud suites based on the control patterns and integrations you need:
- LangGraph: Best for engineers building long-running, stateful custom agents that need durable execution, state checkpointing, and human-in-the-loop approval steps.
- OpenAI Agents SDK: Best for developers who want lightweight code primitives for tool calling, agent handoffs, guardrails, and tracing while supplying their own hosting.
- CrewAI & n8n: Consider CrewAI when a task genuinely benefits from structured multi-agent delegation, or n8n when the job is primarily wiring LLM outputs into existing business apps and webhooks. Always judge these by verified side effects. Adding more agents to a loop doesn’t guarantee better accuracy.
If your organization prefers to buy runtime infrastructure, identity, and governance from its primary cloud vendor, evaluate the major cloud agent suites by how well they integrate with your existing stack:
| Cloud Platform | Choose it when | Key responsibility to verify |
|---|---|---|
| AWS Bedrock AgentCore | You want modular AWS runtime, IAM identity, memory, gateway, and observability services | Selecting and wiring the modular services into your application |
| Google Gemini Enterprise Agent Platform | You want a Google Cloud agent platform that works well with the rest of your Google stack and online evaluation | Configuring runtime access, Vertex AI permissions, and data connectors |
| Microsoft Copilot Studio | Low-code internal or customer agents and native Microsoft 365 / Teams channels matter most | Managing tenant governance, licensing, and connector security |
Compare complete operating costs
Lining up a platform hosting fee, an all-in voice minute rate, and an outcome-based contract side by side produces a misleading spreadsheet. You have to compare the complete cost of the configured stack against the tasks it successfully finishes.
For example, as of November 2026, Vapi pricing starts at $0.05/min for platform hosting while passing STT, LLM, and TTS costs through separately. Retell pricing advertises $0.07 to $0.31/min for voice agents depending on the bundled components you select. Meanwhile, open-source frameworks shift costs into cloud compute and engineering maintenance, and Sierra bills per outcome.
As the paper AI Agents That Matter highlights, evaluating accuracy without cost, or cost without accuracy, leads to bad architecture decisions. Use this worksheet during a bakeoff to normalize quotes across the exact same batch of test tasks:
| Cost Scope | What to Record | Question That Prevents Hidden Costs |
|---|---|---|
| Variable runtime | Platform fees, LLM tokens, STT/TTS minutes, telephony, call recording, and QA add-ons | Which provider charges are bundled vs. billed separately? |
| Fixed & operating work | Base platform minimums, implementation engineering, hosting/on-call, and evaluation tooling | Who pays for and maintains each layer in production? |
| Accepted outcomes | Only the test runs that satisfy both your backend outcome and policy rules | Which calls, API mutations, or diffs actually passed inspection? |
Calculate your true baseline using a single metric across every finalist:
| Cost per Verified Outcome = (Total Relevant Batch Cost) ÷ (Verified Completed Tasks in Batch) |
|---|
Keep a few accounting rules in mind during your pilot:
- Ask about edge-case billing: Confirm how each vendor bills during call silence, warm transfers, hold music, and automated test runs.
- Preserve raw usage units: Record token counts, audio seconds, and call volume so you can recalculate costs if a provider changes its rates.
- Never average zero completions: If a cheap configuration fails every acceptance test, its cost per verified outcome is undefined. Report the spend and 0 verified completions explicitly.
Ask finalists for the same proof of completion
A shared definition of “done” turns separate vendor demos into an objective engineering bakeoff. While every platform offers native debugging tools, relying on each vendor’s internal dashboard makes cross-platform comparisons nearly impossible. Run every finalist through the exact same scenarios, policy rules, and repeatability checks.
Consider a multi-item refund scenario: a caller asks to refund Item A, then adds Item B mid-conversation before confirming. Your company policy requires explicit customer confirmation covering both items before the refund API is called. To grade the call accurately, you have to verify two independent facts:
- Backend state: Did the database actually process refunds for both Item A and Item B?
- Policy compliance: Did the agent secure confirmation for both items before firing the webhook?
That separation between tool-driven state and policy compliance is the exact challenge highlighted by Sierra Research’s τ-bench.
| Observed Evidence | Bakeoff Verdict |
|---|---|
| Only Item A was refunded in the backend | Incomplete task: even if the agent promised both on the call |
| Both items refunded before the caller confirmed | Policy violation: the backend state is right, but required consent failed |
| Both items refunded after explicit confirmation for both | Verified outcome: satisfies both state and policy requirements |
Save the audio recording, transcript, tool-call trace, backend state response, and billable usage for every test run. You can follow our vendor bakeoff guide and voice evaluation guide to set up matched testing conditions.
Running a cross-vendor bakeoff with Coval
When you are comparing multiple voice or chat platforms or migrating between providers, a shared evaluation layer keeps your grading rubric consistent across every candidate:
- Standardized stress testing: Coval’s vendor bakeoffs workflow and simulated conversations throw identical caller personas, edge cases, and metrics at any connected platform.
- Backend verification: Coval’s deterministic API State metric inspects your backend response directly to prove the database changed as expected.
- Calibration: Built-in human review workflows let your team audit grading disagreements and lock in a trusted rubric.
(Note: If you are only prototyping on a single platform, native test tools and manual spot-checks may be enough to start. Add a dedicated evaluation layer when you need to compare vendors head-to-head or enforce regression gates in CI/CD, and budget for it separately using Coval pricing.)
Make a defensible final decision
Cut any platform that misses a hard deployment requirement early, before funding a multi-week pilot. For the finalists that survive, summarize your decision in a one-page purchasing record covering four points:
- Deployment fit: The channels, tool integrations, latency targets, and hosting constraints that narrowed the field.
- Verified completion rate: The side-by-side pass/fail evidence from your test scenarios, including any policy violations that block launch.
- Total operating commitment: Who owns prompt/code maintenance, on-call incidents, and the true cost per verified outcome.
- Open contract blockers: Who will sign off on data retention, log export, security reviews, and outcome-billing definitions.
If you need deeper performance data on specific voice providers, pair this workflow with our 2026 voice platform benchmarks. And if you are evaluating QA and testing infrastructure rather than agent runtime platforms, see our evaluation tools comparison.
Start with a single consequential workflow and require every finalist to prove completion against the same rubric. That turns an impressive sales demo into an engineering decision backed by evidence.