
Voice AI Agent Architecture: A Production Guide
A voice AI agent architecture needs a named owner for audio, tools, state, and release decisions. Use this reference design to find which handoff failed and test it.
Picture a caller who interrupts your voice agent mid-sentence. The audio stops, but the model may still believe it finished the reply, so its next answer assumes the caller heard something they never did. OpenAI’s audio truncation guidance exists for exactly this mismatch. A better model doesn’t decide who stops the playback or how the application recovers.
Choose a voice AI agent architecture by the handoffs your application has to control: telephony, turn-taking, speech models, tools, hosting, and the data you keep. Give each handoff an owner, a signal you can observe, and a test you run before release. This guide builds that ownership map across audio, background work, and backend state, then applies it to a small scheduling deployment tested with Coval, so any failure traces to one responsibility before you expand what the agent can do.
Key takeaways
- Name an owner for every handoff: who stops playback, who commits a booking, and who approves a release.
- Interruption handling depends on the transport: on a WebSocket or Twilio Media Streams, your code must stop playback.
- Tools and background work can propose changes; only your application confirms a booking, after the caller agrees.
- Release on call audio, component traces, and the backend record, not on what the agent said.
A voice AI agent architecture needs owners beyond the model
A voice AI agent architecture is the connected system that turns caller audio into an application decision and an audible reply. It includes the transport, a turn controller, speech and reasoning services, tools, hosting, and the recordings and traces you use to judge a release.
In a cascaded setup, speech-to-text (STT) transcribes the caller, a large language model (LLM) decides the reply, and text-to-speech (TTS) speaks it. Speech-to-speech models can combine those steps, but the ownership questions stay the same.
Draw the audio path from the caller and back to the caller, then draw next to it the operations that can change your application’s records. A scheduling agent has two outputs, what it says and what it books, and they need different checks: a well-phrased confirmation doesn’t mean an appointment exists. This guide uses accepted state for what your application has confirmed and recorded so far, such as the appointment date the caller settled on. The agent can say anything; only the accepted state is what the system treats as true.
Here’s one way to divide the work. A small team may give several roles to one engineer, but the responsibilities stay separate.
| Component | What to assign | Owner |
|---|---|---|
| Telephony and transport | Connection, audio format conversion, playback buffer, disconnects | Platform engineering |
| Turn controller | Deciding the caller is done, handling interruptions, handling silence | Voice engineering |
| STT and reasoning | What was heard, what to say next, which action to request | Voice engineering |
| Tools and conversation state | Which actions are allowed, what the backend returned, where a transaction stands | Integrations |
| TTS and serving | Spoken output, model hosting, capacity | Voice and infrastructure |
| Human escalation | Who takes the call, what they receive, whether the transfer connected | Operations |
| Data pipeline | Which speaker is which, access, retention, deletion | Data and security |
| Evaluation and release | Pass criteria, review of results, authority to roll out or stop | QA and release |
For each handoff, write down what goes in, what comes out, who can reject the result, and which event shows the step finished. Model selection happens inside this map. The voice AI models guide compares the options; your architecture record only needs the interfaces a replacement must keep, such as streaming format, cancellation, and error signals.
The diagram below splits the same design into three paths. Audio runs from the caller through the models and back. Control carries tool calls and background results. Evidence is what you keep to judge the call. One application-owned gate, a check in your code, decides when a tool result or background result may change a booking or the accepted state.
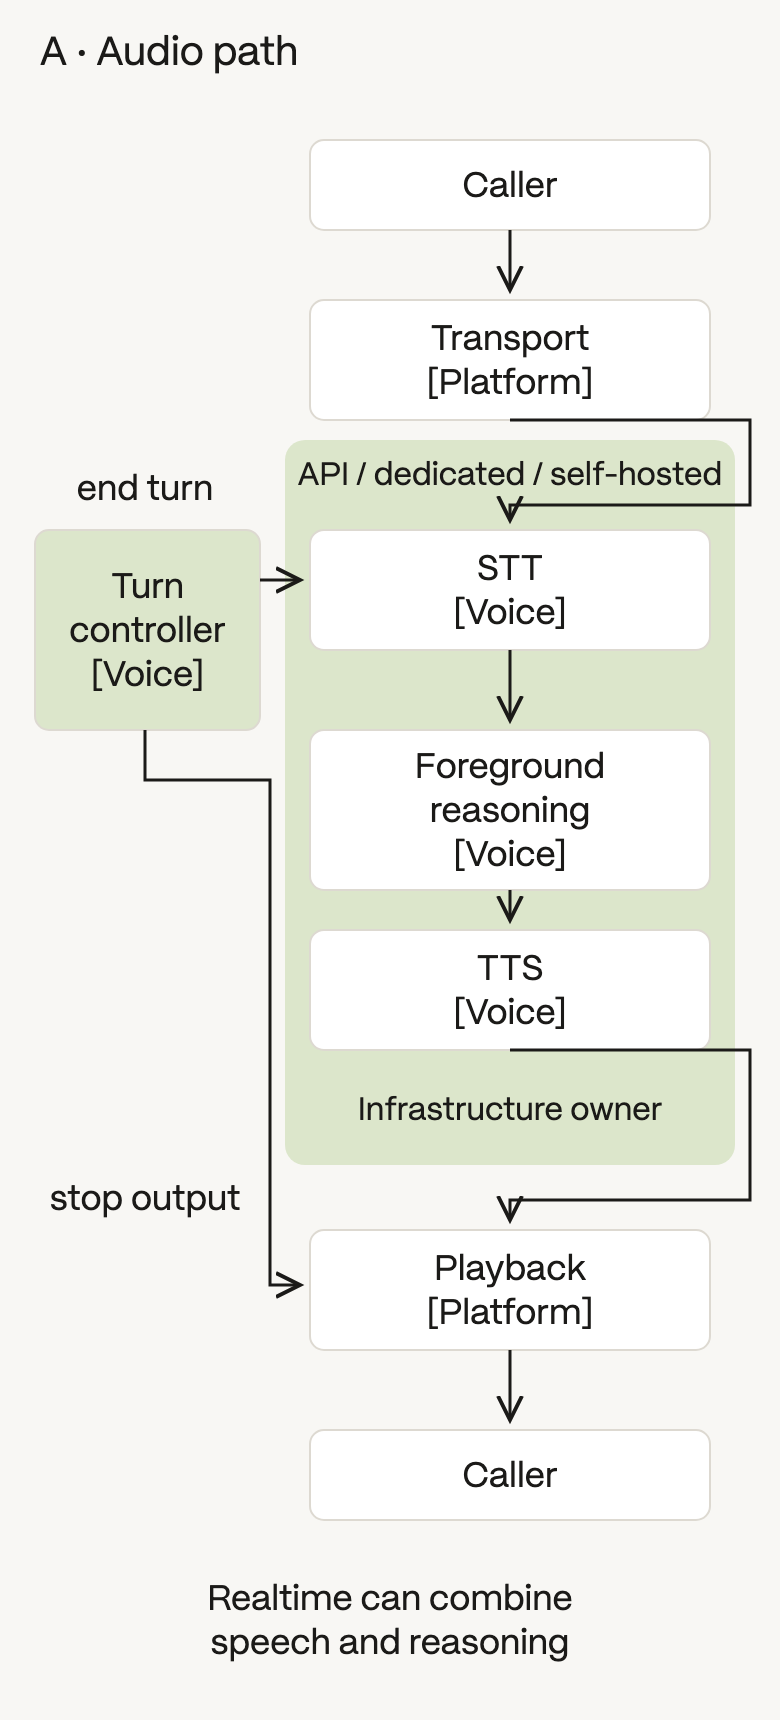
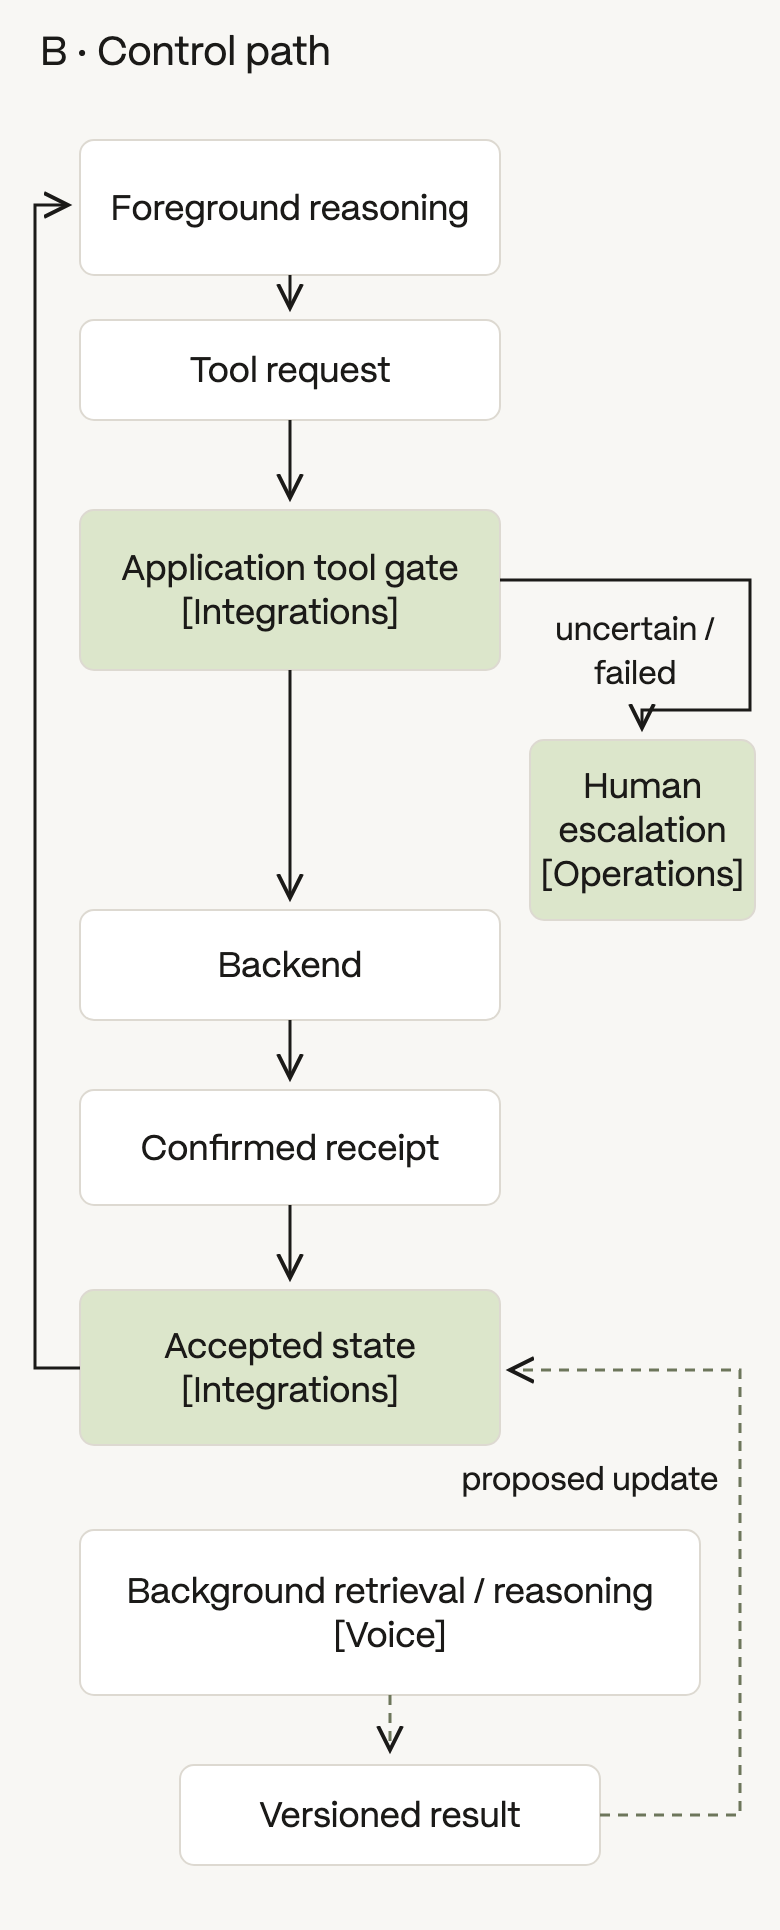
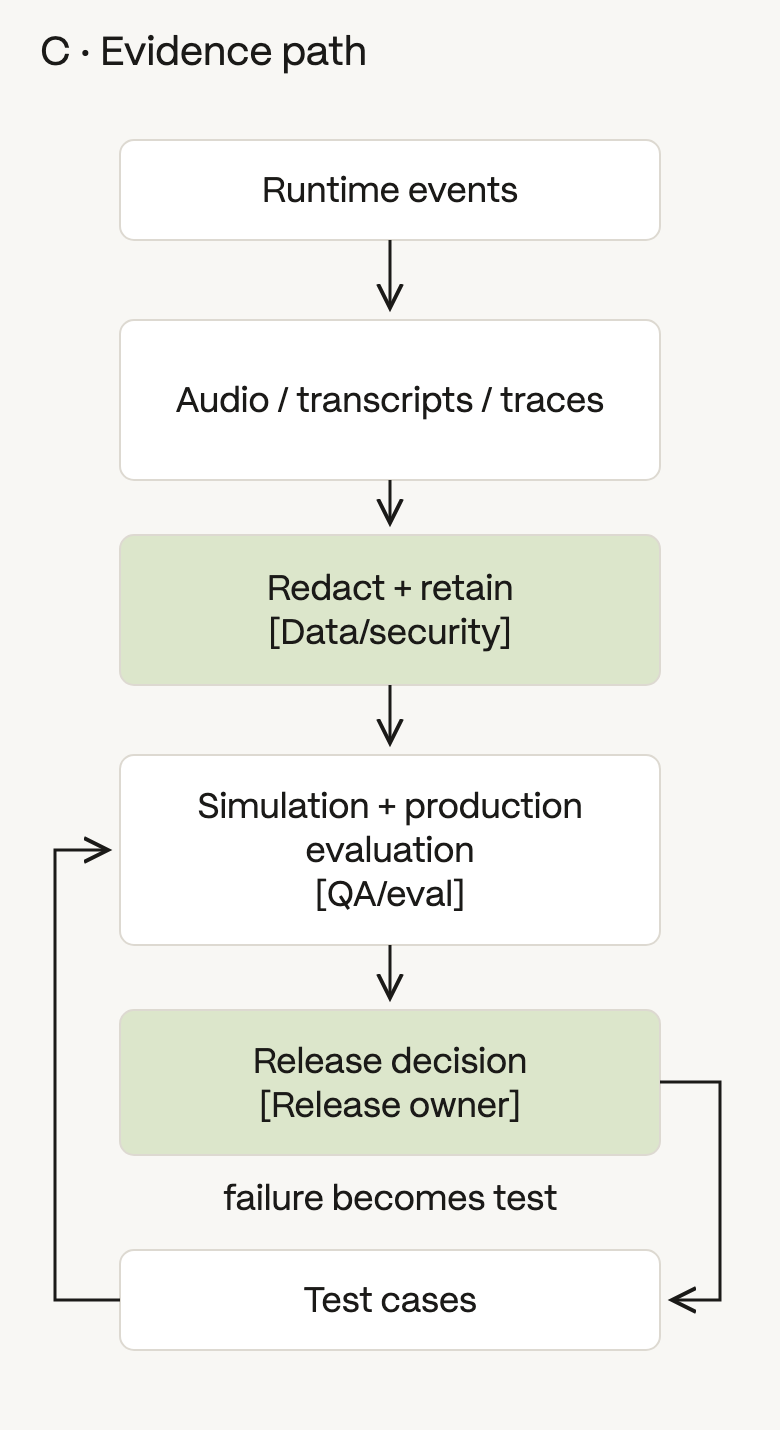
Reference architecture with separate audio, control, and evidence paths. The application owns the gate that approves a state-changing action.
Test the map with one question: for any operation that was rejected or left unfinished, can an engineer name the component that owned it? If the answer is “the agent,” the diagram needs another boundary. Once the owners are clear, you can decide which model steps to combine.
Cascaded and speech-to-speech architectures expose different controls
The two designs differ in which steps your application can see and control. According to OpenAI’s voice architecture guide, a chained (cascaded) system manages speech recognition, the agent workflow, and speech synthesis as separate stages, which makes each stage visible or replaceable.
Realtime speech-to-speech keeps audio and reasoning inside one live model session and supports tools. OpenAI’s guide also describes GPT Live, a model that handles the spoken conversation and delegates reasoning and tool use to a separate backend.
For OpenAI Realtime, optional input transcription runs asynchronously through OpenAI’s transcription endpoint and should be treated as guidance rather than exactly what the model heard. So when you need to know whether the model misheard a caller, keep the audio; a side transcript alone can’t settle it.
| Path | What your application can inspect | Choose it when |
|---|---|---|
| Cascaded | Text between the recognition, workflow, and synthesis stages | You need to swap or benchmark STT on its own, or check each reply against policy before it is spoken |
| Realtime speech-to-speech | One live audio session with tools and session controls | You don’t need to inspect or rewrite text between hearing and speaking, and the call recording plus session events are enough to debug a bad turn |
| Hybrid: fast voice layer plus backend reasoning | A fast voice layer with separate application reasoning | Lookups or multi-step reasoning would otherwise leave the caller in silence |
The hybrid row mixes the two designs: a voice layer up front, with a separate backend behind it doing the reasoning and tool work, as GPT Live does. A hybrid can split the work across as many models as the job needs, and however you split them, the responsibilities stay the same; only the packaging changes. Coval founder Brooke Hopkins, in a September 9, 2026 conversation with Baseten, a model-hosting company, compares those jobs to a self-driving car’s: transcription is perception, reasoning is planning, and the voice or tool calls are the controls. Tianshu Cheng, who leads voice AI at Baseten, describes a split that sits between the two pure designs: an audio reasoning model paired with a separate TTS model.
The speech-to-speech vs cascaded guide examines the choice in more depth. Whichever you pick, write down one reason for each stage you keep: “We need to replace recognition independently” is a reason; “enterprise agents use cascades” isn’t. Every stage you keep also spends part of the same response-time budget.
A voice agent’s latency budget includes hosting and playback
The latency budget has to cover everything between the caller finishing and the caller hearing a reply. Measuring only the reasoning model leaves out endpointing (detecting that the caller has finished speaking), transport, synthesis, and playback.
Twilio’s latency guidance proposes starting targets for a straightforward cascaded agent, not guarantees, so adapt them to your service. The headline is a 1,115 ms median mouth-to-ear target, measured from the moment the caller stops talking to the moment the reply reaches their ear. Of that, 885 ms is the voice agent platform’s share, where the speech-to-text, LLM, and text-to-speech stages run. The other 230 ms is outside the platform, including audio traveling over the internet or phone network. Twilio’s stage targets leave about 60 ms of the platform’s share unassigned:
| Timing | What the target covers | Twilio target |
|---|---|---|
| STT | Recognition | 350 ms |
| LLM | Time to first token | 375 ms |
| TTS | Time to first audio byte | 100 ms |
| Other platform work | The rest of the platform total, not itemized | About 60 ms |
| Platform total | All time inside the agent platform | 885 ms |
Don’t add up vendor headline numbers and call the result a response time. A first token, an audio byte, and audible speech happen at different points, so measure what callers actually experience. Log one call ID and record speech end, the moment the system decides the turn is over, the model request, the first output you can speak, and playback start, noting which clock each timestamp comes from.
Treat serving as its own engineering choice. Our STT benchmark measures Whisper Large v3 on two hosts, and the results show why. Over the 30 days to November 4, 2026, its p50 time to final transcript segment (from the end of speech to the final transcript) was 111 ms on both a Baseten dedicated endpoint and Together AI’s shared API. Its p95 was 248 ms dedicated and 494 ms shared: the same model and the same p50, with twice the tail on the shared host.
With a managed API, measure from your application’s region. With dedicated or self-hosted inference, include queueing, warm-up, batching, and capacity under your expected concurrency. When network hops dominate, test co-locating the stages. Compare placements with the same audio, configuration, and concurrency, record median and tail separately, and count failed calls instead of timing only the completed ones. The latency guide explains the measurement definitions in depth.
Before tuning model response time, find the event that tells the system the caller has finished speaking. Turn detection controls that event, and stopping an existing reply is a separate operation.
Turn detection and playback cancellation need separate owners
Turn detection decides when the agent should answer; playback cancellation decides how it yields when a caller interrupts. LiveKit’s turn-handling documentation offers several ways to decide a turn has ended: a turn detector model that reads meaning and acoustics on top of voice activity detection, the STT provider’s own endpointing, the realtime model’s built-in detection, or manual control. Pick one on purpose instead of inheriting the default.
Write separate tests for a pause, background sound, an intentional interruption, and silence. A caller who says “Tuesday… actually Wednesday” shouldn’t be treated as two separate booking requests. Decide whether the agent waits, asks for clarification, or drops the pending answer.
Who cancels playback changes with the transport. Stopping the sound is only half the job. The other half is truncation, which cuts the model’s stored copy of its reply back to the part that actually played, so its next answer doesn’t assume the caller heard the rest. On WebRTC and SIP, OpenAI’s Realtime server manages the output audio and truncates automatically when the caller interrupts. On a WebSocket, your client stops playback, tracks how many milliseconds played, and tells the server where to cut the reply. For Twilio, Media Streams messages give you two controls: a clear command that empties Twilio’s audio buffer, and marks, labels you send after outgoing audio that Twilio sends back once that audio finishes playing.
| Transport | Who stops playback | What to log |
|---|---|---|
| OpenAI WebRTC or SIP | The server, which also cuts the reply back to what played | The interruption event and the conversation state afterward |
| OpenAI WebSocket | Your client stops playback, tracks how much played, and tells the server where to cut the reply | How much played, and the cut point you sent |
| Twilio Media Streams | Your application sends clear and handles returned marks | The clear command, and which marks came back played versus cleared |
Twilio sends marks back even when a clear empties audio that never played, so a returned mark alone doesn’t prove playback. On the OpenAI side, the docs note that the model can’t precisely align transcript and audio, so a truncation cuts the audio at the point you give and removes the transcript text for the unplayed portion.
Give platform engineering the playback-stop code and voice engineering the reply after an interruption. Test both with a recording and the event sequence, not by checking that voice activity fired. Include queued speech as well as speech already playing, because stopping synthesis alone leaves another buffer to drain.
After cancellation, the next reply has to match what the caller wants now. The model may already have requested work before it yielded, and that work can still return later, so the application needs a rule for whether an interrupted request may change anything.
Background work must never outrun confirmed application state
Background work such as retrieval, slow reasoning, guardrails, and tool calls should only propose results. The application decides which ones change the conversation or the backend. Otherwise a late result can overwrite a correction the caller just made: the caller said Wednesday, and a lookup that started when they said Tuesday comes back and quietly puts Tuesday back.
Google DeepMind’s October 2024 Talker-Reasoner paper splits the agent in two: a fast Talker keeps the conversation going while a slower Reasoner works in the background and writes its conclusions to memory. The Talker usually answers from the latest conclusion instead of waiting, but in one planning phase it waits for the Reasoner. That’s the real design choice: which turns can use the latest result, and which need a fresh one.
Three steps decide whether a late result may change the conversation. A revision ID, a version number for the conversation’s accepted state, makes that choice explicit instead of letting completion order pick which date wins.
- Tag the request. Record the conversation revision and the fields the request used, such as the appointment date, and keep them with the returned result.
- Check on arrival. Compare the result’s inputs with the current accepted state. If the caller changed the date in the meantime, the result is stale even though it succeeded.
- Choose the update. Use a matching result, recompute a stale one, or ask the caller to settle the ambiguity. Only results the application accepts reach the model that’s talking to the caller.
Parallel branches also need an owner for the output. Pipecat’s ParallelPipeline documentation describes independent branches processing the same frames and merging their outputs, but it doesn’t say which branch may speak or write. Give the model that’s talking to the caller sole control of what the caller hears, unless you deliberately build another arbiter.
Tool calls need their own commit step. OpenAI’s function-calling guide separates the model’s request from your application running it and from the model’s follow-up response, and strict schemas constrain the shape of the arguments. A valid schema still doesn’t prove the caller is authorized, the slot is free, or the booking went through.
For a scheduling write, validate the request, attach an idempotency key your application generates (a unique ID, so a retry can’t book twice), set a timeout, and keep the backend receipt. A harmless acknowledgement like “one moment” can keep the call moving while the agent waits, but any success statement has to reflect a confirmed result. What recovery looks like then depends on how far the reply and the backend work had already gone.
Failover depends on how far the response has progressed
A fallback policy has to distinguish a failure before any output, a failure after the caller heard part of a reply, and an unknown backend outcome. Otherwise a replacement service can repeat speech or repeat an action.
LiveKit’s fallback strategies draw the same line. Its agent-level fallback adapters stop switching providers once output has started: TTS fallback is skipped after audio has gone to the speaker, and LLM fallback raises an error once text or tool calls have streamed, unless you turn on retries.
For each failure, decide whether you can discard the partial output, whether the caller already heard it, and whether a tool already ran. A fallback model should receive the accepted state and what already happened, not a reconstructed transcript that assumes the first attempt never occurred. Switching services, as Pipecat’s ServiceSwitcher does on errors the active one can’t recover from, restores a processing path but not the conversation, so test a failure in the middle of a response, not only a provider that’s down before the call starts.
| Where the failure happens | What to do |
|---|---|
| Before the caller heard anything or the backend wrote anything | Retry or switch providers quietly, within a time limit |
| After the caller heard part of a reply | Reconcile what played, then say a recovery line instead of restarting as if nothing was heard |
| Backend result unknown | Look up the booking in the backend before retrying or telling the caller it failed, and hand the call to a human if it’s still unclear |
Sessions also end, on a timer or by design. OpenAI documents a 60-minute maximum for Realtime sessions, and Google’s Live session management describes connections of around ten minutes and audio sessions limited to 15 minutes without compression, with context compression and session resumption to manage those limits. AWS’s Nova Sonic design example deliberately starts a new speech session for each workflow phase and carries earlier context as chat history. Either kind of switch needs the same care: keep the booking’s accepted state and the caller’s authentication outside the model connection, carry forward only the context you’re allowed to retain, give each phase only its own tools, and test what the caller hears at the switch.
Include the human path in recovery: who receives the call, what state they receive, and how you notice a failed transfer. Route unresolved operations there before you widen scope. None of this works unless you recorded enough to tell unheard speech, proposed actions, and committed changes apart, which makes the data pipeline part of the architecture.
The data pipeline needs rules for each artifact
Audio, transcripts, tool-call arguments, and backend receipts carry different risks, so a single “call log” hides them. For each one, decide what it contains, who may access it, and how long you keep it, instead of copying everything into one debugging store.
Knowing which speaker is which matters for scoring later. Twilio’s dual-channel recording puts each party of a two-party call on its own channel. Check your recording provider’s channel mapping instead of assuming the first channel is the agent.
Traces carry content too. When your agent sends OpenTelemetry traces to Coval, each step of the call (STT, the LLM, TTS, a tool call, and a turn) becomes a span, a timed record of that step. Coval’s STT Word Error Rate metric reads the transcript your agent attaches to each STT span, and a tool span can also carry the call’s arguments, so a caller’s words and account details can sit in a trace after the recording has been cleaned. Set retention for each artifact separately, limit who can replay or export it, and include derived copies in deletion: a shorter audio retention period doesn’t remove what was already copied into a prompt trace or a support ticket.
Payments, health data, and outbound calling each add a rule, and your legal and security owners should sign off on every flow. PCI SSC’s audio-recording guidance bars storing card verification codes after authorization, even encrypted, so keep them out of transcripts, model context, and tool arguments as well as recordings. Twilio’s DTMF payment capture sidesteps the problem by taking card digits from the keypad and redacting them from logs. Under HIPAA’s business-associate rule, you need written assurances from every vendor that handles protected health information, wherever it’s hosted. And the FCC’s February 2024 AI-voice ruling treats AI-generated voices as artificial voices under the Telephone Consumer Protection Act, so outbound calls need the called person’s prior express consent unless an emergency purpose or exemption applies. Check consent before dialing.
Our voice AI observability guide covers how to investigate a bad call once these artifacts exist. With the recordings, traces, and receipts in place, you can test the connected system instead of inferring reliability from isolated components. The clearest way to see that is one small deployment.
Deploy one scheduling flow before expanding the call surface
Deploy one inbound appointment flow against a real sandbox backend before adding intents or channels. Take an appliance-repair agent that books a service slot and hands unresolved requests to a human. Coval is purpose-built for testing voice and chat agents and is vendor-agnostic, so its simulation layer can play the caller against whatever stack runs this agent.
Set the scope first. The agent collects the service area, appliance type, available date, contact details, and the caller’s confirmation. Emergency advice, payments, and unrelated account changes stay out of this release. Callers outside that scope get a human, and the operator receives the accepted state, not an unreviewed model summary.
Then test the three failures traced above: a caller who corrects the date, a reply the caller interrupts, and a booking whose result comes back late or not at all.
- Call the deployed agent. Coval’s inbound voice connection calls your agent’s phone number or SIP address, so the test exercises your real handoffs and tool wiring, not just a model prompt. Point the agent at a scheduling sandbox with resettable test data, kept separate from customer appointments.
- Make the callers sound real. Coval’s personas make simulated callers sound like real ones: you configure voices, accents, background noise, and interruption behavior. Vary the caller, with a strong accent, a noisy kitchen, or an interruption during confirmation, and keep the expected booking the same.
- Tie each call to its records. Put the same per-call ID on the traces, the call metadata, and the sandbox receipt, so a failed booking leads straight to its recording and spans. Phone carriers strip custom SIP headers, so Coval’s pre-call webhook sends your agent that ID, with the calling and called numbers, just before each simulated call, and your agent matches it to the incoming call.
- Write down the expected behavior. Book only after the caller confirms, ask again when the date is unclear, and say so when the booking result is unknown. Cover interruption, silence, an unavailable slot, a backend error, and escalation to a human.
- Check the booking itself. Coval’s API State metric checks a backend endpoint you configure after the call, reading a value from the response and comparing it with the value you expect. Point it at a reachable sandbox endpoint that identifies the appointment for that specific test; the result is a match, a difference, or a missing path. Coval’s customers include Chime and Perplexity; Chime, for one, confirms outcomes this way, with a follow-up API call after the simulated call that checks results such as a card’s status.
- Gate the release. Keep the configuration version and test data with the results. A failing check goes back to the component owner before any more traffic.
Write the release rule as a yes/no LLM Judge metric in Coval, which asks a language model to evaluate each simulated call against a question you write: “Did the agent avoid claiming a confirmed appointment when confirmation or the backend receipt was missing?” A NO means the agent claimed a booking it couldn’t back up. API State, from step 5, separately confirms whether the sandbox record exists.
The Coval GitHub Action can run that check in your existing CI workflow. Supply your actual resource IDs and a JSON array of metric IDs that includes the gated metric:
- name: Evaluate scheduling flow
  uses: coval-ai/coval-github-action@v1
  env:
    COVAL_API_KEY: ${{ secrets.COVAL_API_KEY }}
  with:
    agent_id: ${{ vars.COVAL_AGENT_ID }}
    persona_id: ${{ vars.COVAL_PERSONA_ID }}
    test_set_id: ${{ vars.COVAL_TEST_SET_ID }}
    metric_ids: ${{ vars.COVAL_METRIC_IDS_JSON }}
    fail_on_metric_id: ${{ vars.COVAL_BINARY_METRIC_ID }}
    fail_on_metric_value: "NO"
The action fails the job when any simulation returns that value; turn on branch protection if a failed job should block the merge. Commit the script that resets the sandbox alongside the workflow, so every run starts from the same test data. The evaluation guide explains how to build the broader test set.
After booking is reliable, rescheduling and cancellation earn their own test cases because their state changes differ: a reschedule must keep or replace the original appointment according to your backend’s rules, while a cancellation must find the right existing record. Passing this one flow earns a controlled rollout, not permission to expand every intent at once.
A release checklist must name the person who can stop rollout
A release checklist has to say who can stop the rollout, not only what evidence lets it continue. Simulation proves the flow before launch; a canary confirms it holds with real callers, the deployed configuration, and your recording pipeline. After launch, you can submit production calls to Coval to be scored against the same metrics and route the calls your rules flag to human review.
Google’s 2018 canarying guidance defines a canary as a partial, time-limited deployment evaluated against a control. For voice, keep the configuration version and the test scenario each call matches visible in the data you collect, set the traffic share and observation period from your own risk limits, and run long enough to collect comparable calls. Compare the candidate with the control on the booking outcome and on what callers experienced. If the two groups differ in size or mix, or some records are missing, investigate before treating a score change as a regression.
Before you raise traffic, check each of these. If one fails, the named owner stops the rollout:
- Caller intent: the corrected date and the caller’s confirmation appear in the accepted state. Owner: Voice engineering.
- Audible response: an interruption stops the reply, with no mismatch between what played and what the system recorded. Owner: Platform engineering.
- Appointment write: the intended record exists, and any duplicate or unknown write is investigated. Owner: Integrations.
- Recovery and escalation: the operator receives the unresolved details, and your application records whether the transfer connected, not just that the agent announced it. Owner: Operations.
- Data handling: every stored field is correctly attributed and follows its access and retention rules. Owner: Data and security.
- Test coverage: every expected call has a usable result for every criterion. Owner: QA and release.
When a check fails, keep the evidence, pause or roll back according to your deployment policy, and have that owner approve the next candidate. Because each failure points to the boundary that produced it, the owner reviews a specific fix instead of another request to improve the prompt. The CI/CD for voice agents guide explains how to turn those failures into new scenarios, and the enterprise deployment guide covers team resourcing and phased rollout.
This first flow should leave a small review packet: the configuration version, call recordings and traces, backend receipts, and the sign-off or stop decision. Judge platforms by whether they let you produce it.
Choose a platform that lets you own and test every handoff
Choose the orchestration layer by which of these responsibilities it lets you implement and check. A managed platform, a framework, and a realtime model API leave different amounts of work to your team, and none removes the need for accepted state, controlled tool execution, or someone accountable for the release.
| Where orchestration runs | Ask to see in a trial | Pick it when |
|---|---|---|
| Managed agent platform, such as Vapi or Retell | Your tool flow running, an export of call events, and an interruption and a failure | You want to launch quickly and the platform’s event export is enough to debug a failed call |
| Framework application, such as LiveKit or Pipecat | Your code for state, fallback, pipeline events, and deployment | You need control over turn handling, fallback, and state, and have engineers to maintain it |
| Realtime model API, such as OpenAI Realtime or Gemini Live | Session lifecycle, tool permissions, playback ownership, and backend integration | Your calls fit inside the session limits and you can build tool, state, and playback handling around one live session |
Separate building the voice application from building the infrastructure that tests it; the build vs. buy framework covers that second decision. Ask each candidate to run your corrected-date call, an unknown booking result, and a recovery path, and to show the recordings and events afterward. Whichever you choose, account access, healthcare data, and session renewal remain your team’s decisions.
Make responsibility visible before adding complexity
The interruption at the top is a small case of a bigger problem: the model, the caller, and the backend can each believe something different. A production architecture needs a deliberate way to reconcile them. When it works, your team can show what the caller heard, which instruction the application accepted, what the backend committed, and who decides whether recovery is complete.
Start with the scheduling flow and test a corrected date, an interrupted reply, and an uncertain booking. To run those scenarios in Coval, connect the deployed phone or SIP agent and use the trial against your sandbox. Keep the recordings, traces, and backend checks together, so your next architecture decision follows from a failure you can explain.